How Speculative Decoding Speeds Up Inference
A large model generates tokens one by one. A smaller model can draft a short continuation for the larger model to verify in one pass. Speculative decoding exploits the cost difference between checking candidates and generating them from scratch. Drafts enter the output only after acceptance; speed depends on acceptance and verification costs, not just parameter counts.
Contents
Why can one verification advance several tokens?
In ordinary autoregressive generation, later inputs remain unknown until the next token is chosen. A draft model proposes tokens sequentially, giving the target model a known input path whose conditional distributions can be evaluated in one forward pass. Causal dependence remains: the system guesses a path and then checks it.
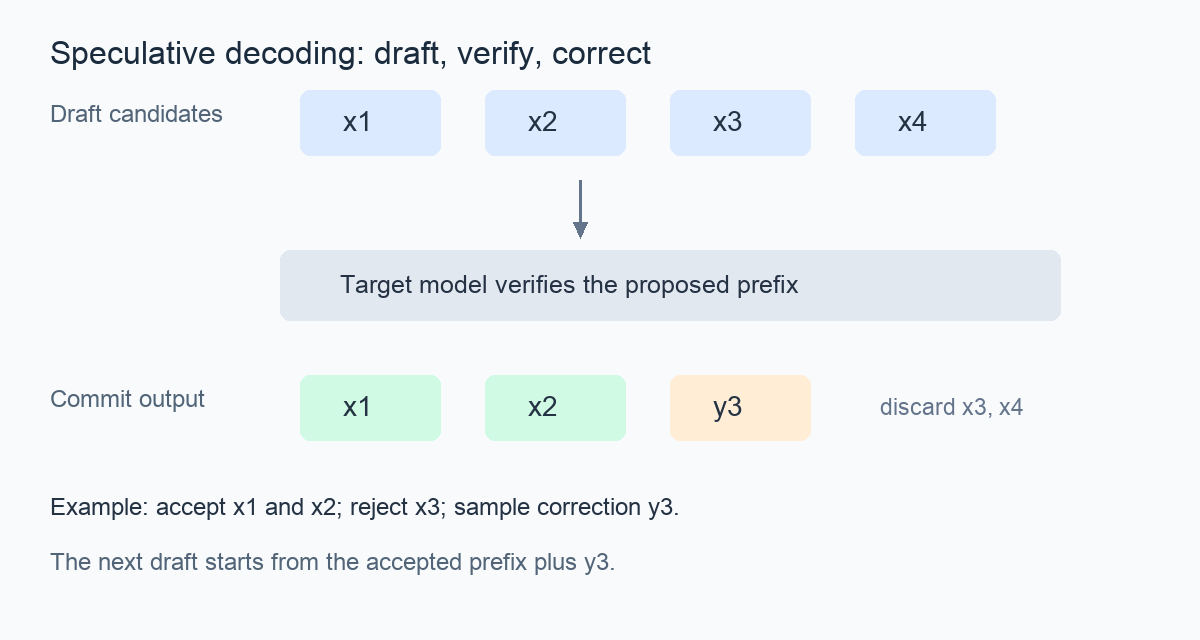
Acceptance advances along a prefix. Once the third candidate is rejected, the fourth cannot be kept independently because it was conditioned on that third candidate. The next round starts from the accepted prefix plus the correction. If the entire draft is accepted, the classic algorithm can sample an additional token from the target distribution. Algorithm 1 in the original paper defines this step.
What does “unchanged output” mean?
Greedy decoding can compare each candidate with the target model’s selection and keep the matching prefix. Random sampling cannot simply require both models to draw the same token: that would change probabilities. Classic speculative sampling uses an acceptance probability and a correction distribution after rejection to preserve the target distribution, assuming exact probabilities and a correct implementation.
Matching distributions does not mean identical sentences on every invocation or identical random-number paths for the same seed across implementations. Floating-point arithmetic, sampling settings, and implementation details can affect actual results. Distinguish greedy-sequence equality from distributional equivalence.
Three candidates explain the acceptance rule
For a fixed prefix, let p be the target distribution and q the draft distribution. Draw candidate x from q and accept it with probability min(1, p(x) / q(x)). A candidate drawn from q necessarily has q(x) > 0. If rejected, resample from a distribution proportional to max(p(x) − q(x), 0). These are the distributions after the intended sampling transformations, not arbitrary raw logits.
| Candidate | Target p | Draft q | Acceptance | Accepted mass |
|---|---|---|---|---|
| A | 0.6 | 0.2 | 1 | 0.2 |
| B | 0.3 | 0.5 | 0.6 | 0.3 |
| C | 0.1 | 0.3 | 1/3 | 0.1 |
The accepted contribution is q(x) × min(1, p(x) / q(x)) = min(p(x), q(x)), totaling 0.6 here. The remaining rejection probability is 0.4. Only A has a positive residual, of 0.4, so a rejected draw is corrected to A. The final probabilities are exactly 0.6, 0.3, and 0.1.
This is more than assuming that the small model is accurate enough. For every candidate, min(p, q) from acceptance plus max(p − q, 0) from correction equals p. The identity explains why correction cannot be omitted. Full-sequence correctness still requires the algorithm to operate on each conditional prefix correctly.
from fractions import Fraction as F

def check(p, q):
    accepted = [min(a, b) for a, b in zip(p, q)]
    residual = [max(a - b, F(0)) for a, b in zip(p, q)]
    rejection = 1 - sum(accepted)
    assert rejection == sum(residual)
    if rejection:
        corrected = [x / rejection for x in residual]
        output = [a + rejection * r for a, r in zip(accepted, corrected)]
    else:
        output = accepted
    assert output == p
    return accepted, rejection, output

p = [F(6, 10), F(3, 10), F(1, 10)]
q = [F(2, 10), F(5, 10), F(3, 10)]
a, r, out = check(p, q)
check(p, p)
check([F(1), F(0)], [F(0), F(1)])
print('accepted mass:', [float(x) for x in a])
print('rejection probability:', float(r))
print('final distribution:', [float(x) for x in out])
The standard-library example uses exact fractions. It was executed and also checked equal distributions and completely disjoint supports:
accepted mass: [0.2, 0.3, 0.1]
rejection probability: 0.4
final distribution: [0.6, 0.3, 0.1]
It verifies single-step probability mass, not a real model, full-sequence generation, or GPU performance. Equal p and q produce no rejection; the code avoids normalizing a zero-mass residual.
A longer draft is not always faster
More candidates can yield more accepted tokens, but drafting costs time and candidates after the first rejection are wasted. Verifying a longer draft is not constant-cost either. Dynamic lookahead decides when to stop drafting instead of proposing many tokens every round.
Hugging Face’s October 8, 2024 introduction describes stopping based on draft confidence and reports experiments on an RTX 4090 with specified model pairs and tasks. These are author-reported results, not experiments reproduced here; the maximum speedup is not a deployment promise.
A useful simplified measurement is total drafting, verification, and management time divided by tokens actually committed in that round, compared with ordinary decoding’s average time per token. This organizes measurements rather than predicts exact speed. Even high acceptance can lose if the extra work is too expensive.
Fix the benchmark conditions first
Choose the target model, sampling settings, and realistic request-length distribution. Measure ordinary decoding’s time to first token, generation time, and peak VRAM before adding drafting under the same conditions. Record average accepted length, drafting time, and verification time at both low and high concurrency. Faster individual requests do not guarantee greater service throughput.
The traditional same-tokenizer pairing makes the probability rules easier to explain. Tools may also support tokenizer alignment or self-speculation. Transformers v5.13.1 documentation distinguishes these paths. Check model, cache, and batching constraints for the actual version; one implementation’s support is not universal.
An independent draft model generally adds weights and runtime state. The target cache must track the committed prefix and handle rejected state. Read alongside KV cache memory estimation and PagedAttention block management: speculation changes generation and verification, while paging changes storage management.
References
- Fast Inference from Transformers via Speculative Decoding, a peer-reviewed ICML 2023 paper and its PDF. This explains an established algorithm, not breaking news.
- Faster Assisted Generation with Dynamic Speculation, a 2024 first-party technical article with experiment conditions.
- Transformers v5.13.1 Assisted decoding, version-specific documentation; check the installed version.
English edition added on October 7, 2026, after the Chinese edition. The article date matches the Chinese edition; it is not the actual time this English edition became public.
Support
If this article helped you, you can support this site.



Click a QR code to enlarge. More options: support page。